GSoC 2026: GraphQL Server For Musicbrainz

Hi everyone, I’m Sreehari, also known online as owlpharoah (op3kay on Matrix). I’m a second year student at IIIT Jabalpur. This summer I worked on the foundations of a GraphQL server in Rust that sits over the MusicBrainz PostgreSQL database, under the guidance of @bitmap and @jadedblueeyes.

The Setting

MusicBrainz already has an XML/JSON API, but getting related data out of it means chaining together inc parameters, and browsing support differs from one entity type to the next. Looking up five artists at once isn’t really possible either.

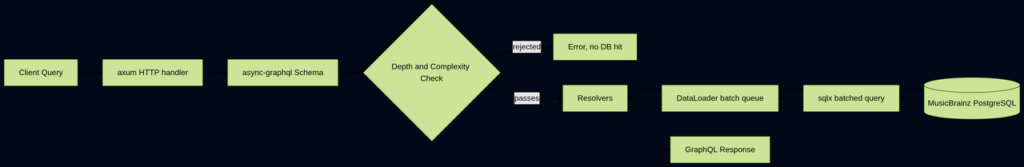
GraphQL fixes most of this by letting a client ask for exactly the fields and relationships it wants in one query. It also lets the server check how expensive a query is before running it, instead of finding out after the database has already taken the hit.

Before writing the proposal, I built a rough prototype covering Artist, Release Group, Release, and Recording, mainly to see how things would click together. Two problems showed up: N+1 queries on relationship fields, and the fact that depth limiting alone doesn’t catch a shallow query that’s still expensive. Both became core parts of the proposal.

The Plan
The proposal scoped the project to six entity types: Artist, Release Group, Release, Recording, Label, and Area. Each would be queryable by MBID, with the usual relationships between them, plus aliases, tags, genres, and ratings across the board.

A few decisions were made initially:

  • DataLoaders would follow a two tier split. One loader maps an entity’s internal id to the hydrated entity itself and gets reused everywhere that entity shows up. A separate, thinner loader maps a parent id to a list of child ids.
  • Fields that need a loader call would live behind ComplexObject, so they only run when a client actually asks for them.
  • Pagination would use keyset pagination instead of offset pagination, since offset pagination gets slow and inconsistent on large tables that change often.
  • Query safety would come from depth limiting plus a complexity weight on every resolver.

key goals

  • A working GraphQL server covering the six entity types
  • Schema level depth limiting and query cost analysis
  • A performance baseline from load testing.

The Result

DataLoader infrastructure is in place across all six entities, following the two tier split. Loaders exist for tags, ratings, artist credit, genres, annotations, aliases, ISNI and IPI identifiers, and MBID to internal id resolution. Hydration loaders are shared across every relationship that points at a given entity instead of duplicated per relationship.
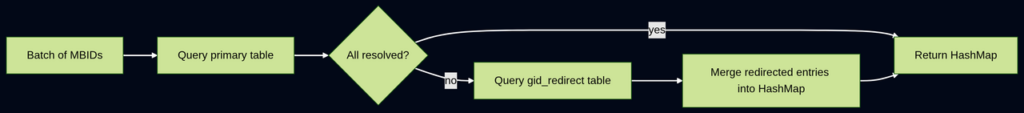
MBID redirect handling lives inside each loader’s load function. When a primary table lookup misses, the unresolved MBIDs get batch queried against the matching *_gid_redirect table, and any hits get merged into the result map. A resolver further up never has to know a redirect happened.

Keyset pagination runs across the paginated fields using ROW_NUMBER() OVER (PARTITION BY parent_id ORDER BY child_id) in a single batched query, so one query can apply a per parent limit across a whole batch of parents. The cursor ended up as a plain integer rather than the opaque string from the proposal.
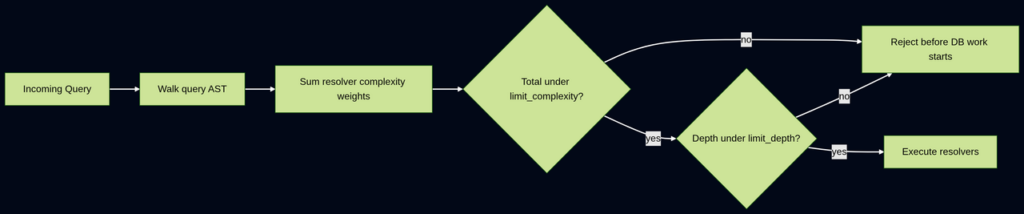
Query complexity weights reflect actual database work: a scalar field costs its default, a single hop DataLoader field costs a flat amount, a paginated one to many field scales with the requested page size, and multi hop fields carry a multiplier on top.

Integration tests cover all six entities.

Week 7’s load testing with k6 turned up two findings worth fixing. There was an N+1 on the isrc field, fixed with a dedicated RecordingIsrcLoader, and a gap in the complexity limiter where a pathological query executed instead of getting rejected outright.

On the infrastructure side, CI runs pre commit hooks and no longer has dead code warnings, and documentation is wired up through Magidoc in Docker compose.

What I Learned

The two tier loader split sounded simple on paper, but it’s saved me a lot of time in practice. Adding a new relationship is now mostly copying hydration logic that already works, instead of writing it fresh.

Fixture data needs to be checked against the database it’s running against, not assumed to be stable. musicbrainz-docker’s sample dumps import non-deterministic subsets of the data, so an MBID that resolves cleanly on my machine can point at something else, or nothing, on someone else’s. That cost me a few confused debugging sessions before I figured out what was going on.

What’s Next

  • Criterion benchmarking, to compare the current per row queries on ComplexObject fields like Release.date against a batched loader variant, and to compare the two hop ArtistCredit and Tags loader patterns against a single joined loader.
  • Moka caching is still an open evaluation.
  • Extended entity coverage beyond the original six.

Conclusion

This was an awesome summer and i enjoyed thinking about and wiring up the API schema and the Postgresql database, fixing bugs, and everything in between. It was really satisfying watching the two tier loader pattern click into place once and then just work for every relationship added after it.

Thanks to my mentors for the guidance, especially on the DataLoader architecture, which I wouldn’t have landed on alone. And thanks to the wider MetaBrainz community for the space to build this in. It’s been a pretty nice summer of query plans, a lot of Rust, and debugging, and I’d do it again.
Picard 3 Release Candidate 4

We received good feedback on the previous release candidate 3, which resulted in several bugfixes and small improvements. The Picard team hence decided to release a fourth release candidate in preparation for the final release of Picard 3.0.

It fixes an important performance issue, so if you are currently running any of previous alpha, beta or release candidate versions upgrade ASAP.
It also fixes issues related to internationalization, causing some of existing translations to not actually show in the application (mainly constants).

Please test, test, and test, report any issue on forums, matrix, or, ideally, on the ticket system. When reporting an issue, always provide details about your environment and a full debug log helps us a lot. Also now is a good time for final review and improvements of the translations.

Download links and a detailed list of changes since Picard 3 release candidate 3 are available below. For a more detailed overview of what is new in Picard 3 please see the previous blog post Picard 3 Alpha Release.

While we have all the major features implemented and with the latest bug fixes we are confident in the current code, this is still a pre-release and there might be bugs. If you use this, do so with care, backup your files and please report any issues you encounter.

If you are updating from Picard 2, note that some of the changes are backward incompatible, hence we recommend you make a backup of your Picard.ini config file before trying this version. You can do so in Picard’s Options under Advanced > Maintenance.

Continue reading “Picard 3 Release Candidate 4”

Welcome Silona Bonewald, new MetaBrainz Foundation Executive Director!

We are very pleased to announce that the MetaBrainz Foundation has appointed Silona Bonewald as Executive Director, following the unfortunate passing of our Rob at the beginning of the year.

Silona has served as Executive Director of IEEE SA Open and Vice President of Community Architecture at Hyperledger, part of the Linux Foundation. Earlier in her career she served as Director of InnerSource at PayPal and authored the widely used O’Reilly publication Understanding the InnerSource Checklist.

Silona also founded the League of Technical Voters, a 501(c)(3) organization dedicated to government transparency through open source technology, and has since advised nonprofit and open source organizations including the Cardano community’s IntersectMBO, the Foundation for Public Code, and the Software Freedom Conservancy. She has served on the board of the Electronic Frontier Foundation’s Austin chapter in the past and holds standing relationships across the world wide standards communities, and more… If you would like to keep browsing Silona’s looong list of professional credentials you are welcome to follow her on LinkedIn.

That’s all a long way to say that we are very excited to have Silona on board! The team is looking forward to working with Silona and you (our wonderful community) to carry Rob’s legacy forward.

Please give Silona a warm welcome in the comments!

Silona will also be hosting an AMA on 5 October 2026, at 17:00 UTC, on the forums (we will do another announcement regarding this, closer to the time), where you can post questions and share with Silona some of your dreams for the future of the MetaBrainz Foundation and its projects!

Continue reading “Welcome Silona Bonewald, new MetaBrainz Foundation Executive Director!”

MusicBrainz Server update, 2026-09-21

Hi! It’s been a while since our last release since we have been working on stability improvements for both website and search to better cope with all the load we are handling recently. The first related changes are part of this release, with more to come, including limiting searches to 500 results (if you need something further down the search, sorry but you probably need a better search!). Additionally, the very annoying bug that sometimes lost track times when parsing tracklists should hopefully be gone now (thanks dvirtz!), and a lot more aggregator and shortener links are now blocked; even when not yet blocked, remember to always add all the relevant destination links rather than redirects and aggregators if possible.

A new release of MusicBrainz Docker is also available that matches this update of MusicBrainz Server. See the release notes for update instructions.

Thanks to derat, dvirtz, ibmibmibm and mib for having contributed to the code. Thanks to DenizC, derat, dvirtz, HibiscusKazeneko, j.rohr, outsidecontext, Raman Sinclair, rinsuki and salo.rock for having reported bugs and suggested improvements. Thanks to AligFu, AndrejsD1718, BestSteve, blueday, Covium, Denatura, EmO686, Flavia Telcean, joao_over9k, Kolesteraw, Life4649, liilliil, mfmeulenbelt, naturbrilian, NorwayFun, Priit Jõerüüt, pXF, syntariavoxmortem, TheParaziT, Vaclovas Intas, vacuousVersifier and wileyfoxyx for updating the translations. And thanks to all others who tested the beta version!

The git tag is v-2026-09-21.0.

Continue reading “MusicBrainz Server update, 2026-09-21”

Picard 3 Release Candidate 3

Today the Picard team is making available a third release candidate for Picard 3. We received good feedback on the previous release candidate 2, thanks to everyone for testing and providing feedback. The final 3.0 release is planned to happen in a few weeks.

Please test, test, and test, report any issue on forums, matrix, or, ideally, on the ticket system.

When reporting an issue, always provide details about your environment and a full debug log helps us a lot.
Also that’s (always) a good time to review and improve translations.

Download links and a detailed list of changes since Picard 3 release candidate 2 are available below. For a more detailed overview of what is new in Picard 3 please see the previous blog post Picard 3 Alpha Release.

While we have all the major features implemented and with the latest bug fixes we are confident in the current code, this is still a pre-release and there might be bugs. If you use this, do so with care, backup your files and please report any issues you encounter.

If you are updating from Picard 2, note that some of the changes are backward incompatible, hence we recommend you make a backup of your Picard.ini config file before trying this version. You can do so in Picard’s Options under Advanced > Maintenance.

Continue reading “Picard 3 Release Candidate 3”

Picard 3 Release Candidate 2

Today the Picard team is making available a second release candidate for Picard 3. We received good feedback on the previous release candidate 1, thanks to everyone for testing and providing feedback. The final 3.0 release is planned to happen in a few weeks.

Download links and a detailed list of changes since Picard 3 release candidate 1 are available below. For a more detailed overview of what is new in Picard 3 please see the previous blog post Picard 3 Alpha Release.

While we have all the major features implemented and with the latest bug fixes we are confident in the current code, this is still a pre-release and there might be bugs. If you use this, do so with care, backup your files and please report any issues you encounter.

If you are updating from Picard 2, note that some of the changes are backward incompatible, hence we recommend you make a backup of your Picard.ini config file before trying this version. You can do so in Picard’s Options under Advanced > Maintenance.

Continue reading “Picard 3 Release Candidate 2”

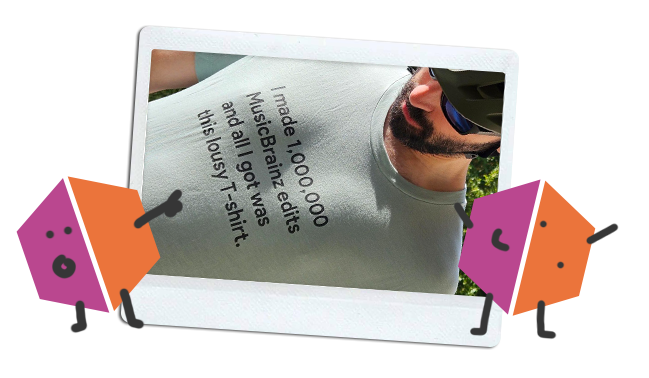
The super special (lousy) shirt plan

Editors are by far MetaBrainz’ biggest and most irreplaceable resource.

They (you) spend countless hours entering data for free, be it for the love of music, to tidy their own collections and listen histories, to support their scenes, to archive historical and cultural data, to apply the cool and soothing editing brain-balm, or a combination of all of the above and more.

Some of the top editors have provided the backbone of MusicBrainz for years, decades, and often perform the more tedious data maintenance and checking tasks.

A few summits ago, the question was asked – can we give these editors, say those with 1 million+ edits, some recognition without getting into the quagmire of things like gamifying?

Enter super special (lousy) shirt plan.

reo showcasing his super special lousy shirt – a real and rare image of a top MusicBrainz editor outside!?
Continue reading “The super special (lousy) shirt plan”

Picard 3 Release Candidate 1

The Picard team is excited to announce the first release candidate for Picard 3. With this release we are confident that Picard 3 is now suitable for testing by a wider audience. The final 3.0 release is planned to happen in a few weeks.

Since we are near a final release, we tried to focus on bugfixes, final changes to the Plugin API and further UI/UX improvements. On the UI side, Picard now fully supports dark / light mode across all supported operating systems, with the ability to change the theme without a restart.

Download links and a detailed list of changes since Picard 3 beta 9 are available below. For a more detailed overview of what is new in Picard 3 please see the previous blog post Picard 3 Alpha Release.

While we have all the major features implemented and with the latest bug fixes we are confident in the current code, this is still a pre-release and there might be bugs. If you use this, do so with care, backup your files and please report any issues you encounter.

If you are updating from Picard 2, note that some of the changes are backward incompatible, hence we recommend you make a backup of your Picard.ini config file before trying this version. You can do so in Picard’s Options under Advanced > Maintenance.

Continue reading “Picard 3 Release Candidate 1”

Search upgrades: Nov 30, 2026

MusicBrainz is announcing a set of upgrades for its search service on November 30, 2026. The main change will be upgrading Solr from version 9 to 10. Fixes and improvements will be released alongside this. Some of these changes may break some specific search requests. Finally, a new feature will be released making it possible to use the search service to search for (musical) genres. See below for more information.

Breaking changes

The following tickets may break search requests in some way.

  • SEARCH-444: Improper ‘relation-list’ in ‘area’ and ‘url’ JSON output. This will be a breaking change for accessing related entities in area and URL search results.
  • SEARCH-642: Drop ‘id’ fields for cdstub and tag. This will technically be a breaking change, but it was broken by design as the values for these search fields are not documented and have never been intended for public use anyway.
  • SEARCH-666: Use quality names rather than numeric IDs. This will be a breaking change for release searches that use quality search field.
  • SEARCH-752: Relationships have an extra ‘target’ property in JSON output. Fixing it by removing the redundant property target will be a breaking change if you are accessing it in search results. The “proper” way to do this is to use the property target-type and access the property id under the property named after this target type.
  • SEARCH-764: Upgrade to Solr 10. This will be a breaking change for mirror owners only, not for search requests. More specifically, it is advised to change the Solr configuration and to re-index the whole MusicBrainz database.

Soft changes

The following tickets will improve search with breaking any requests:

  • SEARCH-452: Index all URL relationships. So far, only URL relationships to Artist and Release were indexed. URL relationships to all other entity types will be indexed too.
  • SEARCH-646: Return exact match first for tag search. It should improve tag search results using indexed Solr search compared to direct Postgres search.
  • SEARCH-677: Include disambiguation of event’s place and work’s recording. Places related to searched events and recordings related to searched works will now be outputted with disambiguation comment, in the same way other related entities are outputted in search results.
  • SEARCH-680: Index genre annotations. It will add genre annotations to the results of annotation search which is already supported for all other annotation-able entity types.
  • SEARCH-681: Support indexed search of genres. It will add “Genre” as a target type for search, just like most other searchable entity types.
  • SEARCH-751: Missing ‘target-type’ property in ‘relationships’ of ‘event’ and ‘work’ JSON output. This will be fixed by adding the property where it is missing.
  • SEARCH-753: Missing ‘target-type’ property in ‘relationships’ of ‘area’ and ‘url’ JSON output. This will be fixed by adding the property where it is missing.

Miscellaneous

A MusicBrainz Server release is also expected to go with some of these changes.

We’ll post upgrade instructions for standalone/mirror servers on the day of the release. If you have any questions, feel free to comment below or on the relevant above-linked tickets.

GSoC 2026: Development of a new Calibre plugin for BookBrainz

Hello, Everyone!

I am Md Waqib Sk (waqib2992 on IRC), an undergraduate student at Indian Institute of Technology Kharagpur. This summer, I had the opportunity to participate in Google Summer of Code 2026 with MetaBrainz, where I worked on developing a calibre plugin for BookBrainz.

I was mentored by Nicolas Pelletier (monkey on IRC). This post summarizes my project, its outcomes, and my experience over the course of the program.

Project Overview

Calibre is a free, open-source e-book manager used to organize and read digital books. My project was about introducing a new plugin that connected calibre with BookBrainz.

The main proposed features of the plugin were:

1. Metadata update: Search selected book from calibre  in BookBrainz database and update it’s metadata accordingly. 

2. Browse BookBrainz: Search editions/public collections by name/bbid  through the plugin and add or download the corresponding metadata.

Plugin Repository: https://github.com/bookbrainz/CaliBBre

Continue reading “GSoC 2026: Development of a new Calibre plugin for BookBrainz”